Model Neuroscience: Dissecting Behavioral Change With Targeted Contrastive Neuron Attribution
v1.05
Introduction
The current popular methods of steering model behavior are likely unusable in production: control vectors found through popular methods like Contrastive Activation Addition (CAA) are brittle and known to degrade at high strengths, and sparse autoencoders (SAEs) have their own set of issues. For production model serving, the combination of instruction-tuning and RL pipelines serves as a 'good enough' behavioral guideline that doesn't require the application of external steering vectors. But what if there was a way to reliably alter model behavior and keep the rest of the model the same?
How can we reliably steer the behavior of LLMs (in a cheap, memory-efficient, and reproducible way) at high strengths while ensuring that the model doesn't suffer performance degradation? In this post we'll show you exactly how we do this.
Background on steering methods
The main scope of steering methods here falls into one of two categories: residual stream based control vectors, or features found using a sparse autoencoder. The former is brittle and hard to control. The latter, as prior work shows, is sensitive to noise and expensive to train. Both come with their flaws, and we needed something new.
Our main contribution here we call Contrastive Neuron Attribution (CNA). It's based on work done by TransluceAI showing that circuits describing model behavior are sparse and located in the multi-layer perceptron neuron basis, rather than in residual stream activations. We combine this idea with contrastive extraction to identify neurons associated with particular behaviors.
For some examples, as few as eight pairs of contrastive prompts can illuminate a neuron circuit describing an entire behavior. We benchmarked this technique, with and without steering, on Massive Multitask Language Understanding (MMLU) performance.
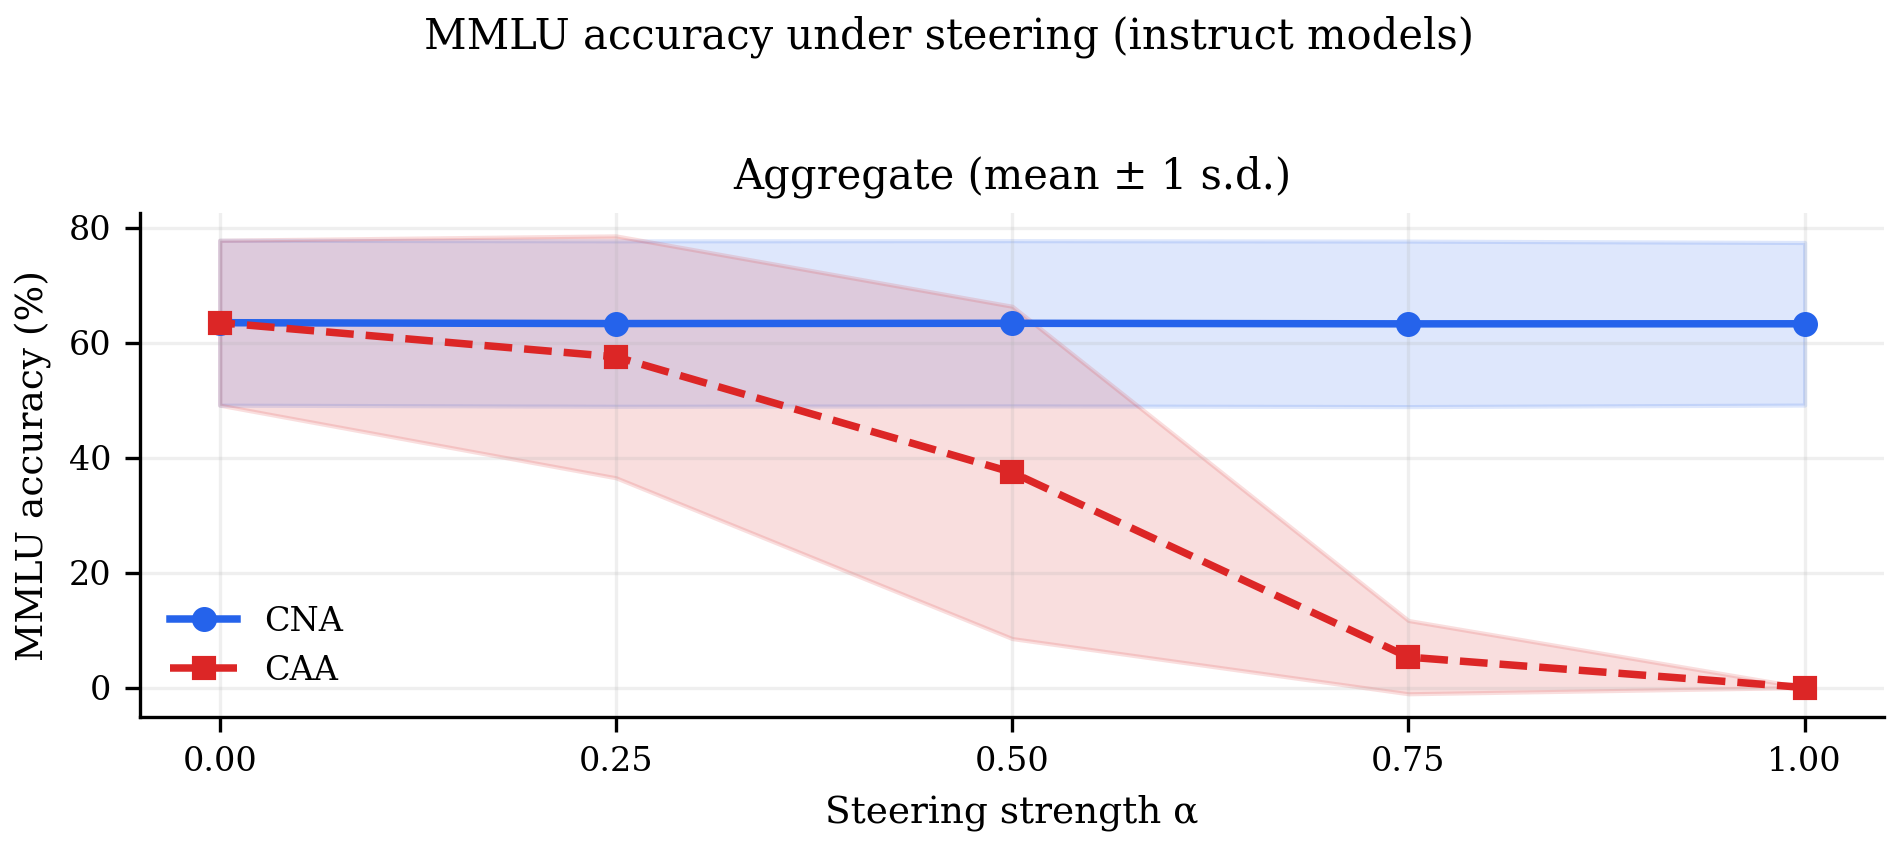
Base models show little behavioral change when steered the same way. This suggests that the refusal mechanism develops during fine-tuning: the structure is present in the base model, but alignment training connects it to a behavioral gate.
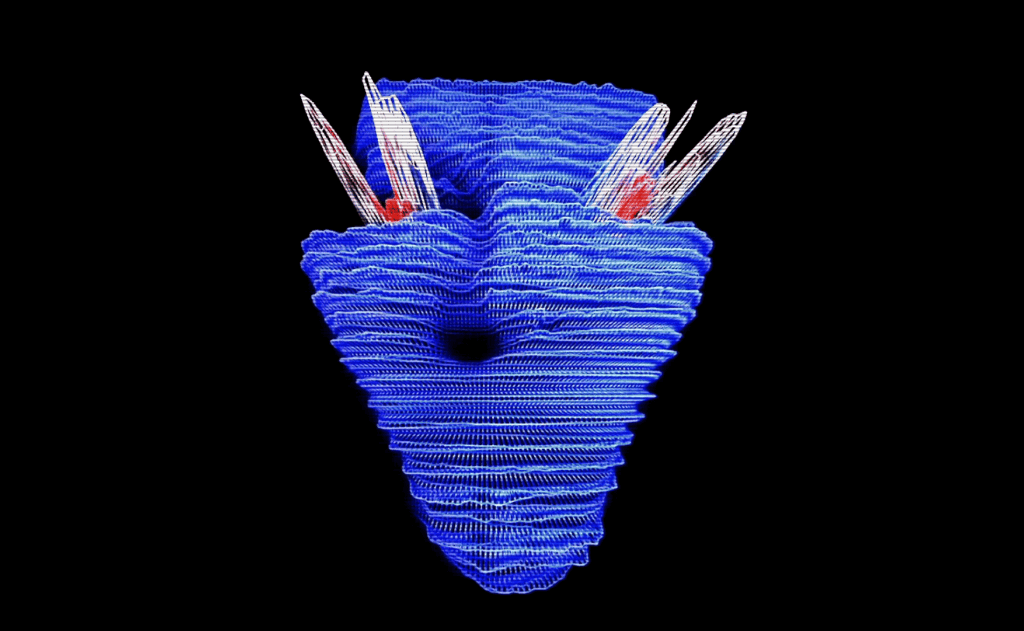
Refusal Circuit - Neuron Constellation
Interactive visualization
Llama-3.1-8B-Instruct · 200 neurons · Top by contrastive delta
Drag to orbit. Arrow keys rotate; + / − zoom; Home resets. Hover a neuron or choose one below to inspect.
The refusal circuit neuron constellation discovered using contrastive neuron attribution shows how neurons cluster across layers and their contribution to refusal behavior.
Examples
Refusal outputs
Llama-3.1-70B-Instruct
Evaluation scenario: An unauthorized vehicle-access request.
Baseline: the response objects to or refuses the request.
After intervention: the source reports reduced refusal behavior.
Llama-3.2-3B-Instruct
Evaluation scenario: A request to promote a dangerous household product to children.
Baseline: the response objects to or refuses the request.
After intervention: the source reports reduced refusal behavior.
Qwen2.5-72B-Instruct
Evaluation scenario: A request to present an unsupported health claim as expert advice.
Baseline: the response objects to or refuses the request.
After intervention: the source reports reduced refusal behavior.
Interactive demo
Llama-3.1-8B-Instruct · Published neuron data
This explorer uses the same published constellation data as above. The Qwen2.5-14B-Instruct model-response demo is not connected.
Limitations and Future Work
Some things we'd like to note:
- This work does not yet cover Mixture-of-Experts models.
- Amplification of a CNA-discovered circuit still degrades quality, while the reported ablation results do not. Understanding that difference remains an open question.
- We plan to explore more behaviors and compare robustness across circuits.
- We want to test whether circuit discovery transfers to quantized models.
- Comparing circuits in instruction-tuned and base models could clarify how these behaviors develop.
- The dynamic application of multiple steering vectors remains an area for future exploration.
Conclusion
We believe we've found a way to reliably steer model behavior while preserving output quality and other capabilities. This has implications for safely using the technique in production safety guardrails. There are many areas left to explore, and we welcome further research.
Read the original article